Reduce Splunk ingest costs before the data reaches Splunk
Filter, drop, redact, and route telemetry at the OpenTelemetry Collector layer using LinkMesh. Keep the data you need. Stop paying to ingest the data you don’t. Self-hosted, vendor-neutral, and priced per collector — not per gigabyte.
Splunk’s value is real, but its ingest-based pricing means every low-value log costs as much to land as a critical one. These are the reasons the bill grows faster than the signal.
You pay to ingest, not to use
Splunk bills by the gigabyte ingested. Every health-check line and debug log costs the same to land as the events you actually query.
Noise dominates volume
Readiness probes, polling chatter, retry storms, and duplicated fields make up a large share of most log pipelines — indexed, retained, and rarely read.
The forwarder can’t filter much
The Universal Forwarder ships what it’s pointed at. Meaningful reduction means transforming telemetry upstream, not at the destination.
PII you can’t un-index
Sensitive fields slip into logs and get indexed in Splunk, where they’re retained and queryable long after they should have been dropped.
One backend for everything
Security-relevant logs and low-value debug output go to the same expensive index, because there’s no layer deciding what belongs where.
No safe way to cut
Nobody drops data in production without a way to see exactly what a filter removes first. So the volume — and the bill — keeps growing.
First: which pricing model is your contract on?
Splunk sells two, and they reward opposite behaviour. Everything below depends on which one you are measured by, so it is worth settling before estimating anything.
Ingest pricing — daily indexed volume
A single dimension: you buy a daily volume in advance and are measured against it each day. The busiest day therefore matters more than the monthly average, and a month that looks comfortable can still contain a day that went over.
What moves it: filtering moves this directly, and a rate limit at the collector protects the peak. Reducing the average while leaving the spike in place is the common mistake.
Workload Pricing — Splunk Virtual Compute
Capacity is measured in SVCs, driven primarily by how much searching you do and how complex it is, alongside indexing volume. The provisioned SVC count sets the ceiling of the system.
What moves it: volume reduction helps less here. The honest answer is that dashboards, scheduled searches and their time ranges are the bigger lever — a Splunk-side change, not something a telemetry pipeline can do for you.
Mechanics as Splunk documents them, not as we would like them to be — check them against your own contract, which may differ. Splunk pricing models. Telemetry reaches Splunk through the collector’s splunk_hec exporter, so every change below happens before that exporter runs.
Reduce at the source, before Splunk
LinkMesh manages the processing that happens on your collectors. Telemetry is filtered, sampled, and masked where it’s produced, then only what you choose is routed to Splunk — the rest goes to cheaper storage or nowhere at all. Your telemetry never passes through LinkMesh.
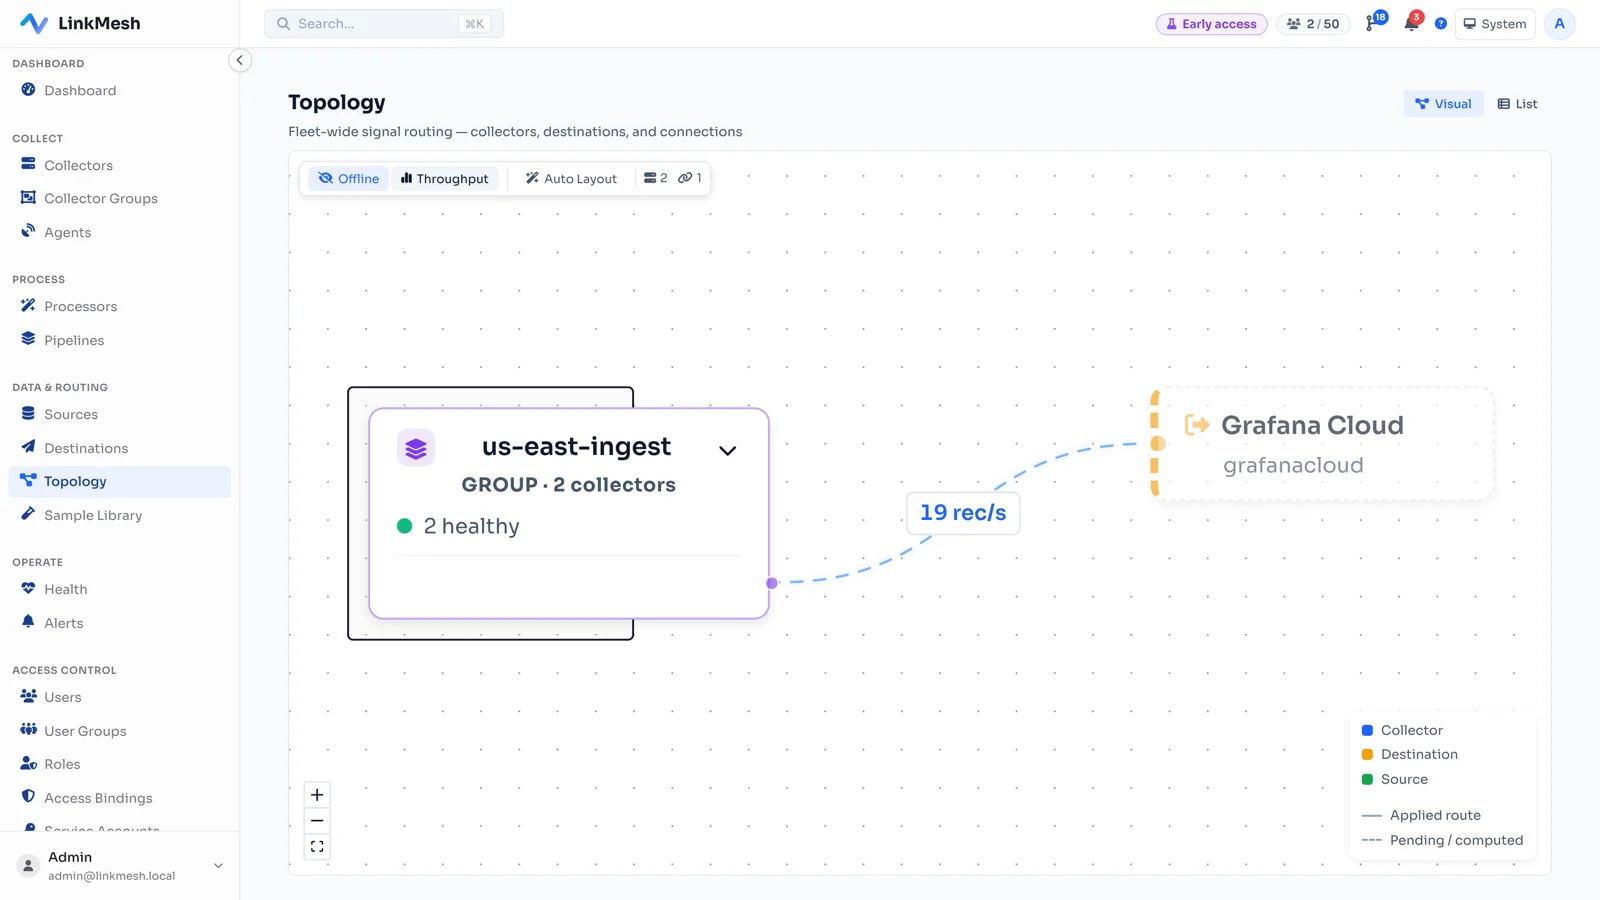
Filtering happens on the collectors; only selected telemetry reaches Splunk. LinkMesh manages the processors and stays out of the data path.
Estimate your savings
Enter your own volume and cost per GB. Everything is editable, and every figure is an estimate for planning — LinkMesh does not set or represent Splunk pricing.
Estimated annual impact
Current Splunk ingest
—
Volume removed
—
Backend savings / year
—
− LinkMesh licence / year
—
Estimated net saving / year
—
Estimates only, for planning. Actual savings depend on your data, contract, and how aggressively you filter. LinkMesh does not set or represent Splunk pricing.
01
Drop the logs Splunk shouldn’t index
Problem
Health checks, readiness probes, and polling noise are ingested and indexed at full price, then almost never queried.
LinkMesh
Write filter rules that read plainly — drop where service.name = "health-check" — and apply them at the Collector, before anything reaches Splunk. LinkMesh renders the rule to OTTL and pushes it across the fleet.
The noise never reaches a billed index. Same signals, a fraction of the volume.
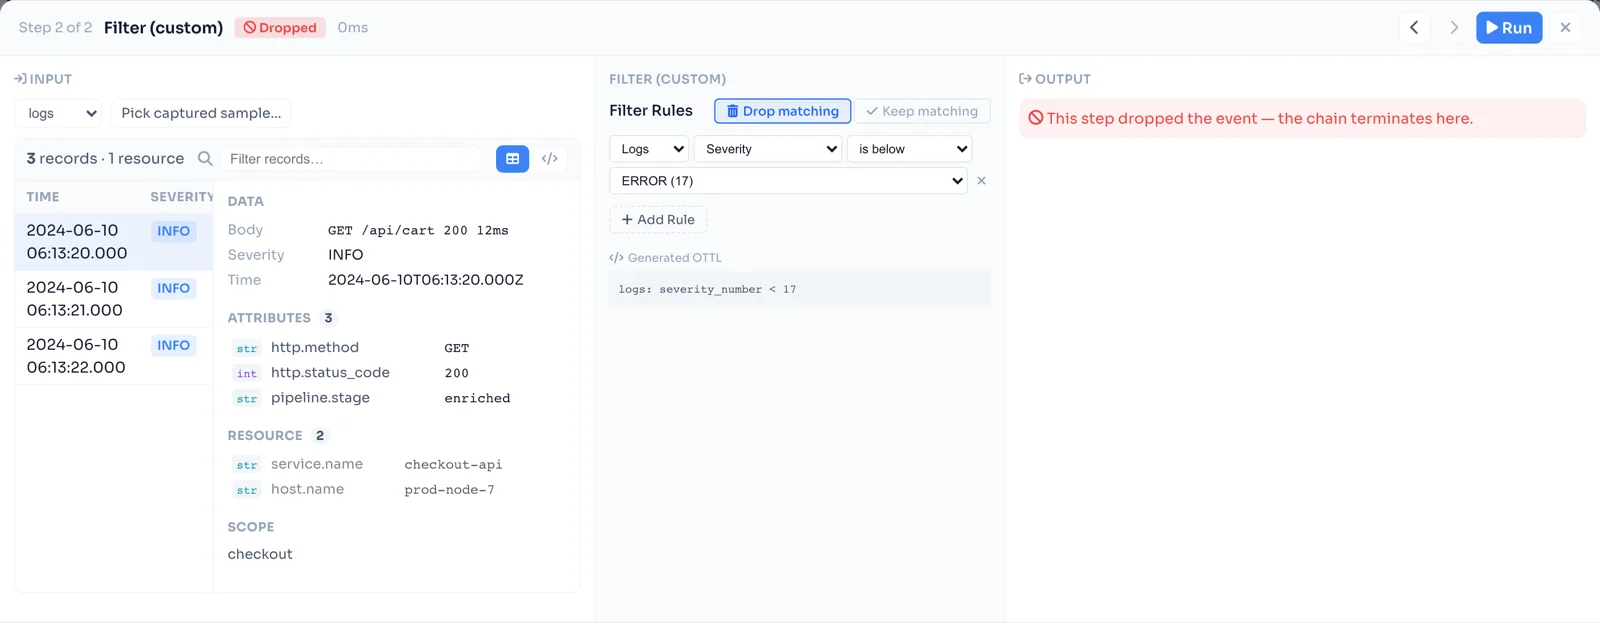
Preview a real record through a drop filter — input, rule, and output side by side — before you ship it.
02
Filter and sample before ingest
Problem
Debug output and high-cardinality, high-volume events multiply your ingest without a matching increase in value.
LinkMesh
Keep debug locally or route it to cheap storage; statistically sample repetitive events; trim duplicated and unused attributes that inflate every record. All at the source, as managed processors on the collector.
Send Splunk the events worth indexing — not every retry and every field.
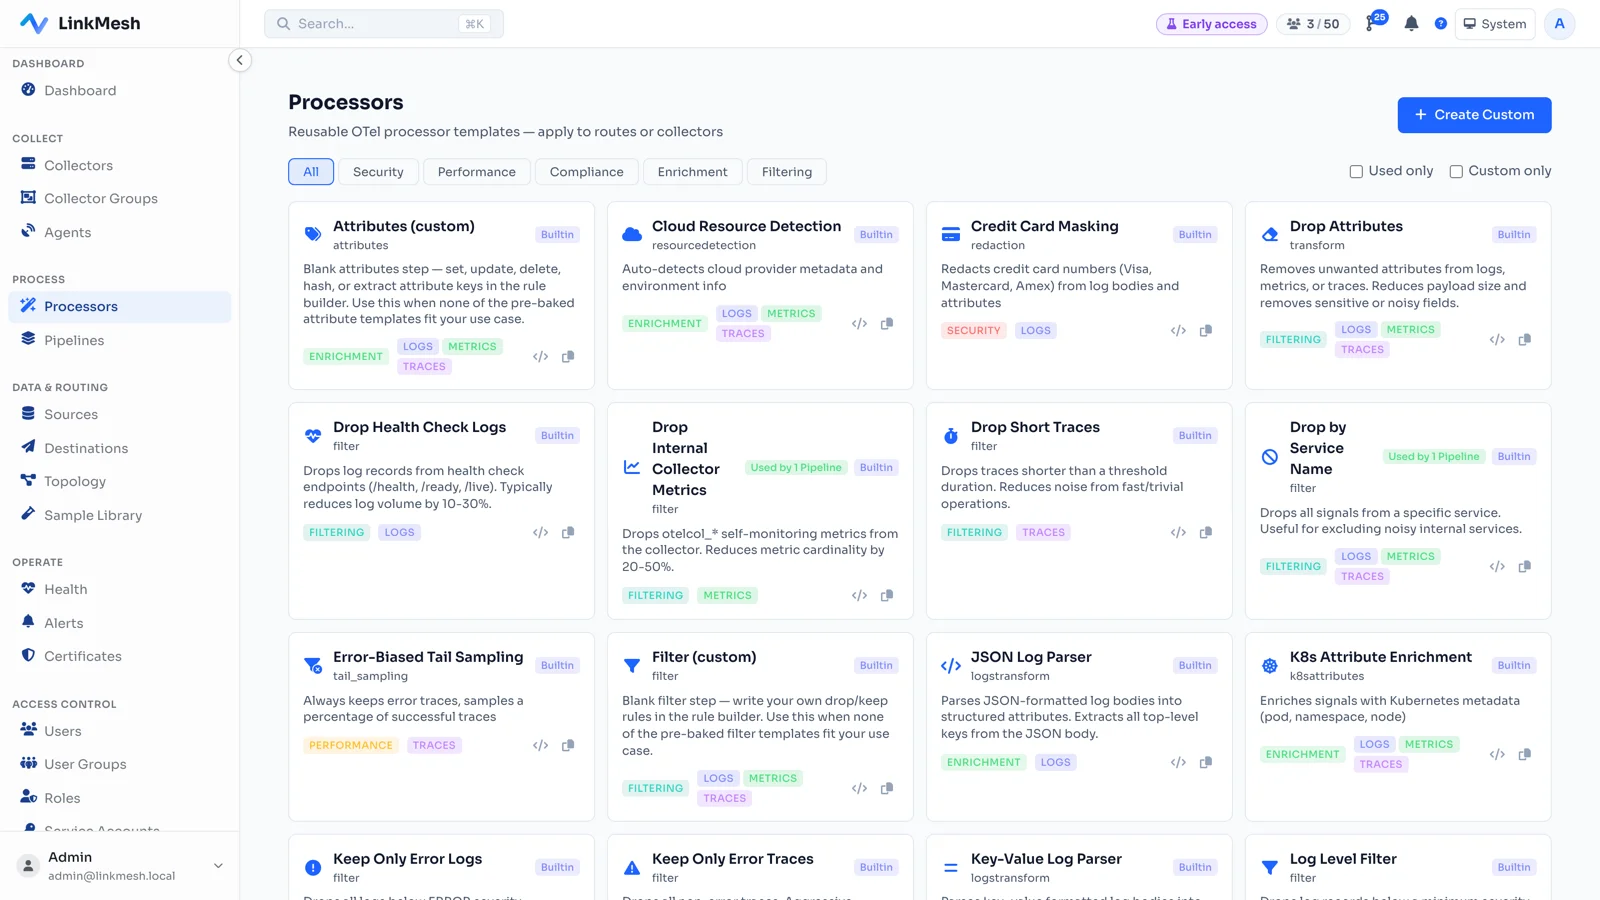
A library of filtering, sampling, and masking processors — attach them to a collector or a whole group.
03
Route selectively — Splunk for what matters
Problem
When one pipeline sends everything to Splunk, low-value telemetry pays the same premium as your security-critical logs.
LinkMesh
Define routes by label, source, or environment: send security-relevant logs to Splunk and fan the rest to object storage, a cheaper backend, or an OTLP destination — from the same collector, with a different processing chain per route.
Splunk keeps the data that belongs there; everything else stops paying Splunk prices.
Route by label or environment: Splunk for security logs, cheaper storage for the rest.
04
Redact PII before it’s indexed
Problem
Credit cards, emails, tokens, and IDs slip into logs and get indexed in Splunk, where they’re retained and queryable by people who shouldn’t see them.
LinkMesh
Apply masking processors on the host, before telemetry leaves your network. Built-in templates for common patterns plus custom OTTL rules for your fields — so sensitive values never reach the index.
Sensitive data is gone before egress — not something to scrub from Splunk later.
Nobody drops data in production on faith. Without a way to see what a rule removes, the safe choice is to ingest everything — and keep paying.
LinkMesh
LinkMesh previews each processor against real captured records: input on one side, the rule and generated OTTL in the middle, the output on the other. You see exactly what a filter keeps and drops before it reaches a single collector.
Cut with confidence, because you saw what the rule does before it ran.
A cost project shouldn’t become a rip-and-replace migration — and coupling every collector directly to Splunk makes any future change a fleet-wide rewrite.
LinkMesh
LinkMesh sits in front of Splunk as a vendor-neutral collection and processing layer built on standard OpenTelemetry Collectors and Grafana Alloy. Splunk stays your backend; LinkMesh manages what reaches it — and the same layer can route elsewhere the day you want to.
Lower the bill now without locking yourself to any one backend later.
Left alone, none of this gets cheaper: the volume grows on its own, the data that already left cannot be recalled, and each agent added is one more to remove later.
Once it is running
A per-collector bill that a volume spike does not move.
Sensitive fields masked on the host, before anything leaves the network.
Every config change a diff you can review and roll back.
Backends you can swap, because nothing proprietary sits in the path.
Common questions
How does LinkMesh reduce Splunk ingest cost?
By filtering, dropping, sampling, and routing telemetry at the OpenTelemetry Collector layer — before the data reaches Splunk. Splunk bills by ingested volume, so removing low-value data at the source directly reduces what you pay to ingest.
Does LinkMesh replace Splunk?
No. LinkMesh sits in front of Splunk as a collection and processing layer. Splunk stays your backend; LinkMesh manages the collectors and controls what telemetry reaches it. The same layer can also route telemetry to other backends if you choose.
Will I lose data I actually need?
You decide what is dropped. Every filter is previewed against real records — input, rule, and output side by side — before it reaches a collector, so you see exactly what is kept and removed. You can route lower-value data to cheaper storage instead of dropping it.
Does my telemetry pass through LinkMesh’s cloud?
No. LinkMesh is self-hosted and carries only configuration and health. Filtering runs in your own collectors, and your telemetry flows straight from them to Splunk or your other backends — it never transits LinkMesh.
How much can I save?
It depends on your data and how aggressively you filter — measure health-check noise, debug logs, and other removable records in a representative sample before estimating savings. Use the calculator on this page with your own GB/day and cost per GB to estimate it. LinkMesh does not set or represent Splunk pricing.
How is LinkMesh priced?
By managed collector, never by data volume. The first 25 collectors are free after a no-card registration in the OpenSight Customer Portal (5 without one); beyond that it is a flat USD 12.50 · CHF 12.00 · EUR 12.50 per collector per month, billed annually, and the bill stops growing at 200 collectors. Your savings scale with volume; your LinkMesh cost does not.
Stop paying to ingest what you don’t use
Self-hosted, vendor-neutral, priced per collector. Stand LinkMesh up, preview your filters against real records, and cut ingest with confidence. The first 25 Collectors are free after a no-card registration in the OpenSight Customer Portal (5 without one).
RHEL / Rocky / AlmaLinux, collector enrollment, and the full walkthrough: Install guide →
Start with one test collector.
Save the current configuration, connect one collector and verify a real signal in your backend. Test one change and its rollback before expanding to the fleet.
No email required for the download. Includes failure tests, rollback and checks for ingest-cost assumptions.
A note about analytics
LinkMesh uses Google Analytics and PostHog to understand which pages are useful. Until you accept, PostHog collects only anonymous, cookieless usage data; session replay is enabled only after consent. Cookie details.